Cylentrix delivers enterprise Managed IT Services that bring IT infrastructure management, 24×7 helpdesk and end-user support, cloud operations, endpoint and patch management, backup and business continuity into one team and one SLA. AI-driven monitoring and automation catch issues before your people feel them; certified engineers keep the digital workplace running. Every engagement starts with an assessment of the estate you already run, not a hardware quote.
Certified infrastructure partners and global compliance certifications behind every managed IT engagement.
Eight operating surfaces, one runbook, one team accountable for uptime end to end.
Most enterprises do not have a technology problem. They have an operations problem. Servers sit with one vendor, endpoints with another, cloud with a platform team, and the helpdesk with whoever picks up first. Every asset works. Nobody owns the outcome.
Cylentrix runs the enterprise as one technology environment with eight operating surfaces: networks, cloud infrastructure, endpoints, users, servers, applications, data and facilities, kept secure, optimised and continuously available through AI-assisted monitoring, IT automation and enterprise-grade operational support. We act as an extension of your IT team, and every engagement carries a dedicated account manager, a written SLA and quarterly reviews of performance, capacity and cost.
LAN, WAN and Wi-Fi monitoring, switch and firewall administration, link uptime.
Provisioning, monitoring and cost optimisation across AWS, Azure and GCP.
Device lifecycle, MDM enrolment, patching and remote software deployment.
24×7 IT helpdesk, Microsoft 365 support, onboarding and offboarding.
Business application support, update cycles and vendor coordination.
Physical and virtual server administration, capacity and uptime management.
Backup schedules, replication, restore testing and disaster recovery drills.
Data centre, colocation, cabling and facilities IT run to enterprise baselines.
Take one service to close a specific gap, or combine several into a fully managed IT programme under a single SLA. Each links to full technical detail, scope and deliverables.
24×7 network and infrastructure monitoring from our Network Operations Centre. Event correlation, proactive alerting and SLA-backed response before users notice a fault.
Learn more
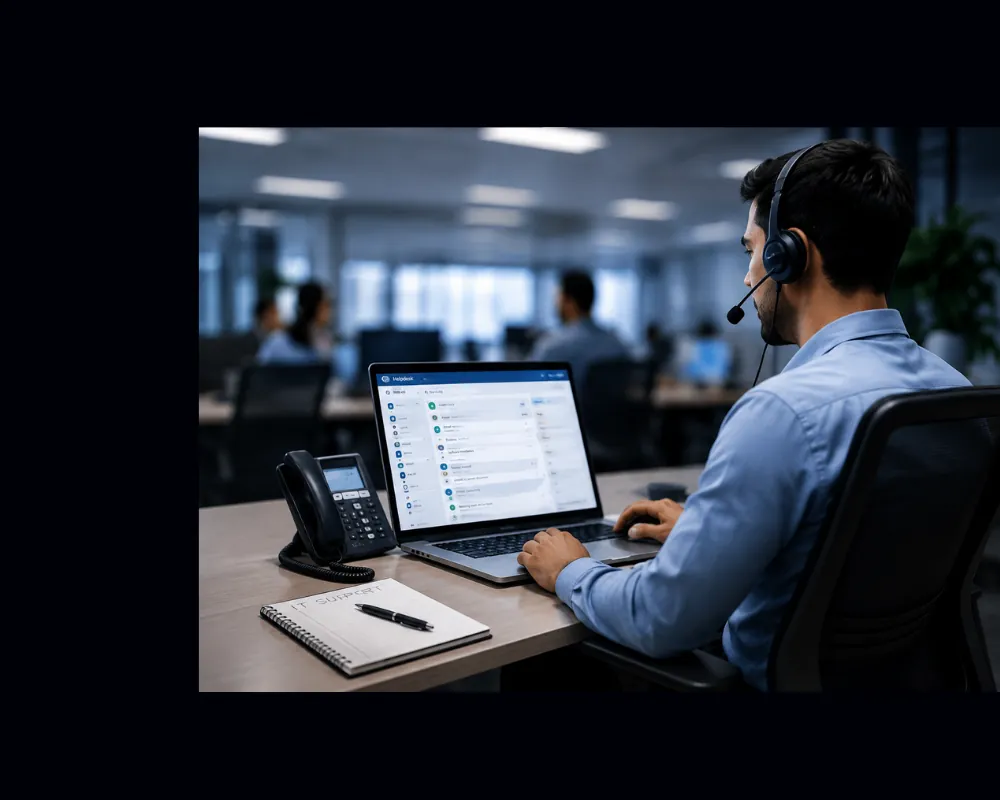
L1–L3 service desk by phone, portal, email and chat, with defined response and resolution targets, remote and on-site support, and CSAT tracked on every ticket.
Learn more
Device lifecycle management across laptops, desktops and mobiles: MDM and Intune enrolment, imaging, software deployment, Microsoft 365 administration and remote wipe.
Learn more
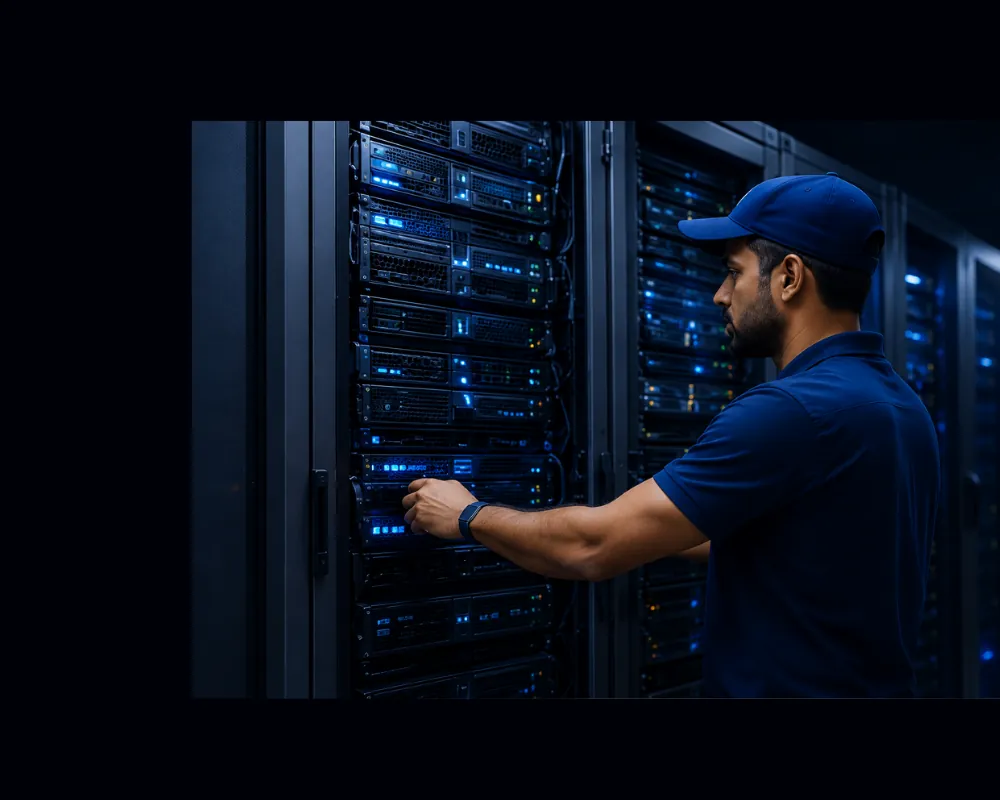
Annual maintenance contracts covering servers, networking and end-user hardware, with preventive service visits, spares management and guaranteed repair turnaround.
Learn more
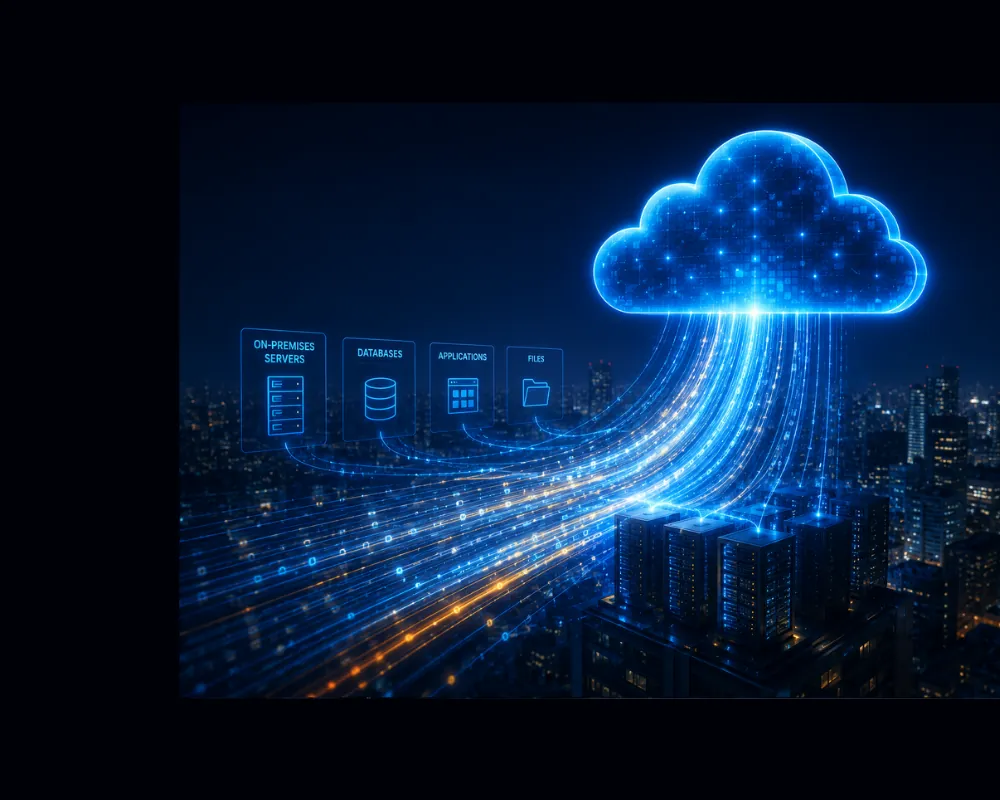
Assessment, landing-zone design and phased migration waves to AWS, Azure or GCP, with dependency mapping, cutover rehearsal and post-migration validation.
Learn more
Day-two cloud operations: provisioning, performance and cost optimisation, capacity planning and 24×7 monitoring across single and multi-cloud estates.
Learn more
Design, build and operation of enterprise data centre environments: racks, power, cooling, cabling and remote hands under documented change control.
Learn more
Tier III and Tier IV colocation with migration planning, smart-hands support, environment monitoring and carrier-neutral connectivity options.
Learn more
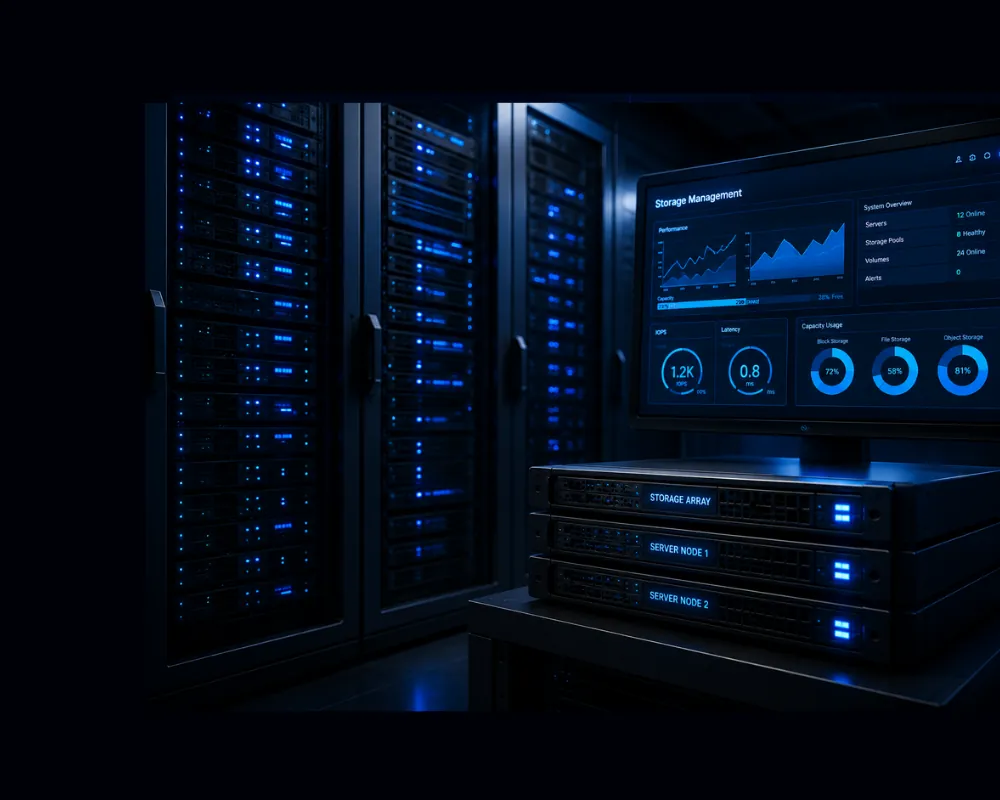
Administration of physical and virtual server fleets and SAN/NAS storage: provisioning, firmware baselines, capacity forecasting and performance tuning.
Learn more
VMware and Hyper-V design, consolidation and lifecycle management, including host patching, cluster balancing and licence-aware capacity planning.
Learn more
Policy-driven backup across endpoints, servers and cloud with immutable copies, defined RPO/RTO targets and scheduled restore drills that prove recovery works.
Learn more
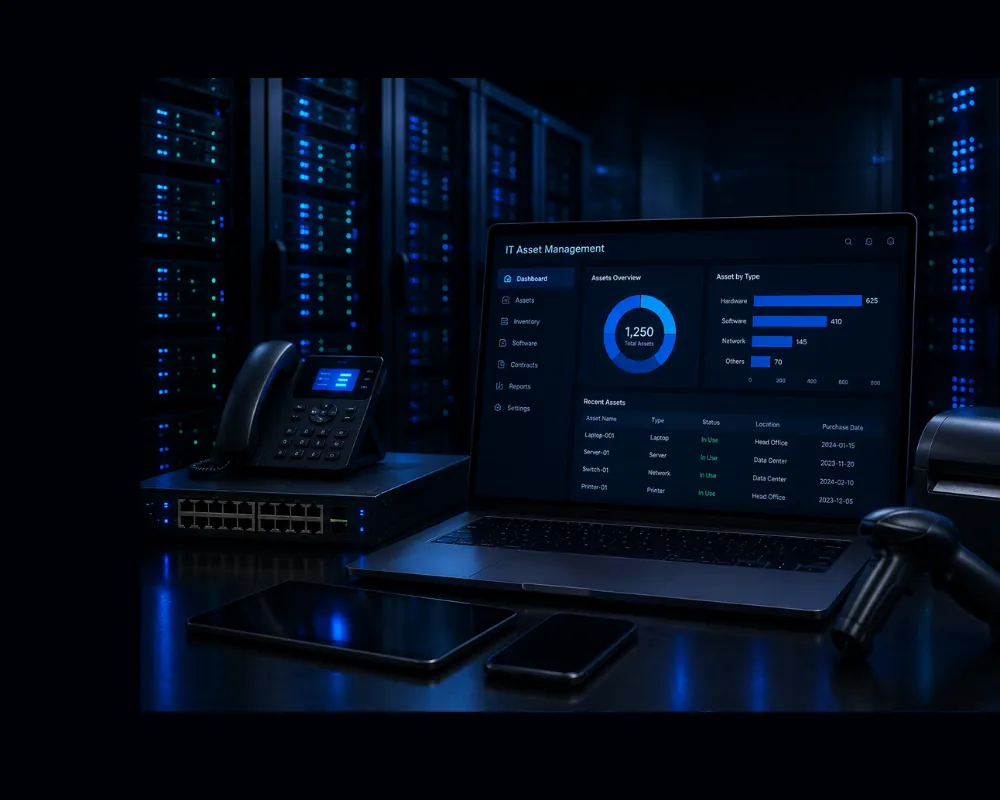
Live hardware and software inventory from procurement to disposal: warranty and AMC tracking, licence compliance and audit-ready refresh planning.
Learn more
Copper and fibre cabling design, installation and certification for offices, plants and data centres, documented to TIA standards with as-built drawings.
Learn more
IP camera design, deployment and managed monitoring with NVR and VMS administration, retention policy management and health checks on every feed.
Learn more
Meeting-room AV, access control integration, sensors and building IoT, deployed and managed as part of the same monitored enterprise estate.
Learn moreSelect a service line to see the operational problem it solves in a real environment, and how Cylentrix runs it day to day.
Infrastructure grows faster than the team that runs it. Servers, switches, links and storage accumulate across sites, monitoring is partial, and the first sign of a failing component is usually a user-reported outage.
We put the entire estate under 24×7 NOC monitoring with AI-assisted event correlation, so a degrading disk, saturating link or failing PSU is fixed as a ticket rather than lived as downtime. Firmware baselines, capacity forecasts and documented change control keep the environment predictable.
Employees lose hours to slow, unstructured IT support: tickets vanish into a shared inbox, there is no ownership, no SLA and no data on what keeps breaking, so the same issues return every month.
A structured L1–L3 service desk with response and resolution targets by severity, reachable by phone, portal, email and chat. Every ticket is categorised and trended, recurring faults are engineered out at the root, and CSAT is measured on every closure, not sampled.
Hundreds of laptops, desktops and mobiles in unknown states: inconsistent builds, missing updates, unmanaged software and no clean way to provision a joiner or wipe a leaver’s device.
Cloud-managed endpoint lifecycle through MDM and Intune: standard images, policy-driven configuration, automated software deployment and remote wipe. Devices stay compliant and supportable wherever the user works, from onboarding to retirement.
Cloud bills climb while nobody owns day-two operations. Workloads are over-provisioned, tagging is inconsistent, backup coverage is assumed rather than verified, and hybrid estates are run from separate consoles.
We run AWS, Azure and GCP as one managed environment: 24×7 workload monitoring, right-sizing and cost optimisation, governed provisioning, and verified backup across cloud and on-premises. Monthly reporting ties spend to capacity so finance and IT see the same picture.
Patching is everyone’s job and therefore nobody’s: updates are applied ad hoc, servers wait months for maintenance windows, and audits find critical fixes missing on systems everyone assumed were current.
A disciplined patch cycle across operating systems, firmware and third-party applications: risk-ranked scheduling, tested rollouts in defined windows, automated deployment with rollback, and compliance reporting that shows exactly what is patched, where, and when.
Backups run, but restores are never tested. RPO and RTO exist on paper only, and the first full recovery attempt happens during a real incident, when it is too late to discover the gaps.
Policy-driven backup with immutable copies across endpoints, servers and cloud, mapped to agreed RPO/RTO targets per system. Scheduled restore drills and documented DR runbooks prove recovery works before you need it, keeping business continuity a fact rather than a hope.
Nobody can say how many devices exist, what they cost, which warranties are live or which licences are compliant. Refresh decisions are guesses and every audit becomes a spreadsheet archaeology project.
A live asset register from procurement to disposal: hardware, software, warranty and AMC status in one system. Licence positions are reconciled continuously, refresh cycles are planned against real age and failure data, and audit evidence is a report, not a project.
Skilled engineers spend their days on password resets, user provisioning and repetitive checks. Manual work does not scale, introduces errors, and leaves no time for the projects that move the business.
We automate the repeatable: AI-assisted alert triage, self-service password reset, scripted provisioning and deprovisioning tied to HR, scheduled health checks and auto-remediation for known faults. Engineers handle exceptions; automation handles the routine, around the clock.
A seven-stage operating cycle with defined artefacts at every stage, so you always know what has been done, what is next, and who owns it.
Inventory servers, network devices, endpoints, cloud accounts and licences. Establish what you actually run before anything is recommended.
Review health, capacity, patch levels and single points of failure. Findings ranked by downtime risk and business impact.
Target-state architecture, service scope and phased roadmap. Deliverables include HLD, LLD, SLA matrix and RACI.
Monitoring agents, documentation, runbooks and helpdesk transition rolled out in phases, with zero disruption to daily operations.
Telemetry into the NOC, AI-assisted alert correlation tuned to your environment, and SLA-backed 24×7 triage.
Incidents and requests resolved through the L1–L3 desk under agreed severity targets, with root cause recorded on every repeat fault.
Quarterly review of uptime, ticket trends, capacity and cost. Automation extended wherever the data shows repeatable work.
Cylentrix runs your complete IT function: tooling, staffing and outcomes end to end. Suited to organisations without an in-house IT team.
Your team keeps ownership and platform; we supply 24×7 monitoring, night and weekend coverage, and specialist engineering on demand.
Fixed-scope design and implementation covering cloud migration, server refresh, office build-out or data centre move, with handover and documentation.
Annual maintenance contracts on hardware you own, plus vendor-neutral architecture review and IT strategy advisory for the CIO office.
A hospital, a plant floor and a data centre carry different uptime constraints, regulators and support hours. From manufacturing to BFSI to data centre estates, we run IT to the sector, not to a template.
Core banking uptime, RBI-aligned operational discipline, branch IT rollouts and audit-ready change and asset records.
HIS, PACS and diagnostic system availability, medical device support and a 24×7 helpdesk paced to clinical shifts.
Plant-floor IT and OT-adjacent support engineered around line uptime, shift patterns and the real cost of a stopped line.
Multi-shift service desks, client-audited delivery environments and seat scaling that keeps pace with project ramp-ups.
Empanelment-aligned delivery, data-localisation-aware infrastructure and long-cycle AMC support across distributed offices.
Campus networks, labs and high-volume BYOD support, with exam-period reliability treated as a hard uptime constraint.
Store-in-a-box rollouts, POS and billing uptime, and infrastructure that absorbs festive-season traffic without drama.
Warehouse, hub and fleet system support, EDI and partner integrations, and connectivity kept alive across every site.
Five infrastructure vendors, each with certified engineers on staff. Recommendations stay vendor-neutral: if the right answer is to extend the hardware you already own rather than buy new, that is what we will tell you.
VMware vSphere and Lenovo ThinkSystem estates: sizing, deployment, consolidation and day-two managed operations under change control.
Cisco Catalyst, Meraki and Aruba campus and branch networks, monitored 24×7 with configuration baselines and firmware discipline.
HPE ProLiant and Dell PowerEdge fleets with PowerStore and vSAN storage: firmware baselines, capacity forecasting and lifecycle refresh.
Engineers hold current VCP, CCNA/CCNP, HPE ASE and Dell Technologies credentials, revalidated on each vendor cycle.
IT services, manufacturing, energy, pharmaceuticals, hospitality, infrastructure and education groups rely on us for managed security, managed IT and connectivity.
Nine differences that show up in day-two operations, not in a capability matrix.
A staffed NOC rota across follow-the-sun shifts, not an alert queue reviewed the next morning.
Current VMware, Cisco, HPE, Dell, Lenovo and Microsoft credentials, kept live through annual recertification.
We are not a single-vendor reseller. If extending the hardware you already own solves the problem, we say so.
A named owner for your environment who knows the estate, chairs the reviews and is accountable for the SLA.
Written response and resolution targets by severity, reported monthly, with commercial consequences attached.
Critical outages get immediate escalation to senior engineers, with pre-agreed authority to act and a live incident bridge.
AI-assisted alert triage, auto-remediation and scripted provisioning handle the routine, so engineers work on what matters.
Certified delivery across AWS, Azure and Google Cloud, from migration to day-two operations and cost governance.
Tested backup, DR runbooks and multi-region delivery across India, the USA and Singapore, so recovery is proven, not assumed.
Published by the Cylentrix Research Office: field data from managed NOC operations, cloud migrations and enterprise IT programmes.
Whitepaper
How AI-assisted monitoring, auto-remediation and predictive maintenance are reshaping enterprise IT operations, and what to adopt first.
Strategy whitepaperRead report
Research Report
What an hour of unplanned downtime actually costs across BFSI, manufacturing and healthcare, drawn from managed operations data.
Annual studyRead benchmark
Guide
Assessment, landing-zone design, wave planning and cutover rehearsal: the sequencing that moves workloads without breaking production.
Implementation guideRead guide
Case Study
How proactive NOC monitoring, patch discipline and tested recovery took a manufacturing group from monthly outages to measured uptime.
Manufacturing · IndiaRead case study
Executive Brief
Predictable IT costs, outsourcing models and the build-versus-buy decisions in front of every CIO office planning the next three years.
8 pages · Board levelRead brief
Technology Report
Where the digital workplace is heading: cloud-managed endpoints, smart offices and the infrastructure hybrid work actually needs.
Technology outlookRead reportThe questions IT leaders ask us most often, answered directly. If yours is not here, a 30-minute call with an engineer will cover it.
Ask a specific questionManaged IT Services are the proactive, ongoing management of your technology environment by a specialist partner. Networks, cloud infrastructure, endpoints, users, servers, applications and business systems are monitored, maintained, patched and supported under a written SLA, so problems are prevented rather than fixed after they take the business down.
By catching problems before they become outages. Cylentrix combines 24×7 infrastructure monitoring, AI-assisted alerting that correlates events across servers, network and cloud, disciplined patch and change management, capacity planning, and tested backup and disaster recovery. Most incidents are resolved from the NOC before users ever notice them.
Yes. Our Network Operations Centre monitors servers, network devices, cloud workloads, storage, backup jobs and business applications 24×7×365 across follow-the-sun shifts, with severity-based response SLAs and escalation to certified engineers rather than an unattended alert queue.
Yes. We operate hybrid estates spanning on-premises data centres, colocation facilities and AWS, Azure and Google Cloud. Provisioning, monitoring, cost optimisation, capacity management, backup and disaster recovery run as one environment under one team and one SLA, not as separate silos.
Yes. Microsoft 365 administration, tenant security baselines, Exchange Online, Teams, SharePoint and OneDrive support, Intune endpoint management and licence optimisation are part of our digital workplace service, backed by the same helpdesk that handles every other end-user request.
Yes. We maintain a live inventory of hardware and software assets from procurement to disposal: warranty and AMC tracking, licence compliance, refresh planning and audit-ready reporting, so finance and IT are always working from the same numbers.
An IT assessment typically starts within five working days of scoping. Full managed services onboarding, covering discovery, documentation, monitoring agent rollout and helpdesk transition, usually runs two to six weeks depending on estate size, with no disruption to daily operations.
Yes. Remote and hybrid employees receive the same support as office users: cloud-managed endpoint enrolment, remote patching and software deployment, secure access, and a helpdesk reachable by phone, portal, email and chat wherever the person is working.
Yes. Many clients run Cylentrix as their complete IT function: helpdesk, infrastructure, cloud, vendor management, procurement guidance and IT strategy under a dedicated account manager. Others keep an internal team and use us for 24×7 coverage, specialist skills or specific service lines. Both models carry the same SLA discipline.
Pricing is a predictable monthly fee, typically per user or per device, scoped to the service lines you take: monitoring, helpdesk, endpoint management, cloud operations, backup and DR. Scope, SLA and pricing are agreed in writing after the assessment, so there are no surprise invoices when something breaks.
The assessment is a working session, not a sales call. A Cylentrix engineer reviews your current infrastructure, support model and recovery posture, identifies the risks that matter most, and gives you a prioritised view of what to fix, whether or not you engage us afterwards.
Tell us what you are trying to run. We will match you with the right engineer.